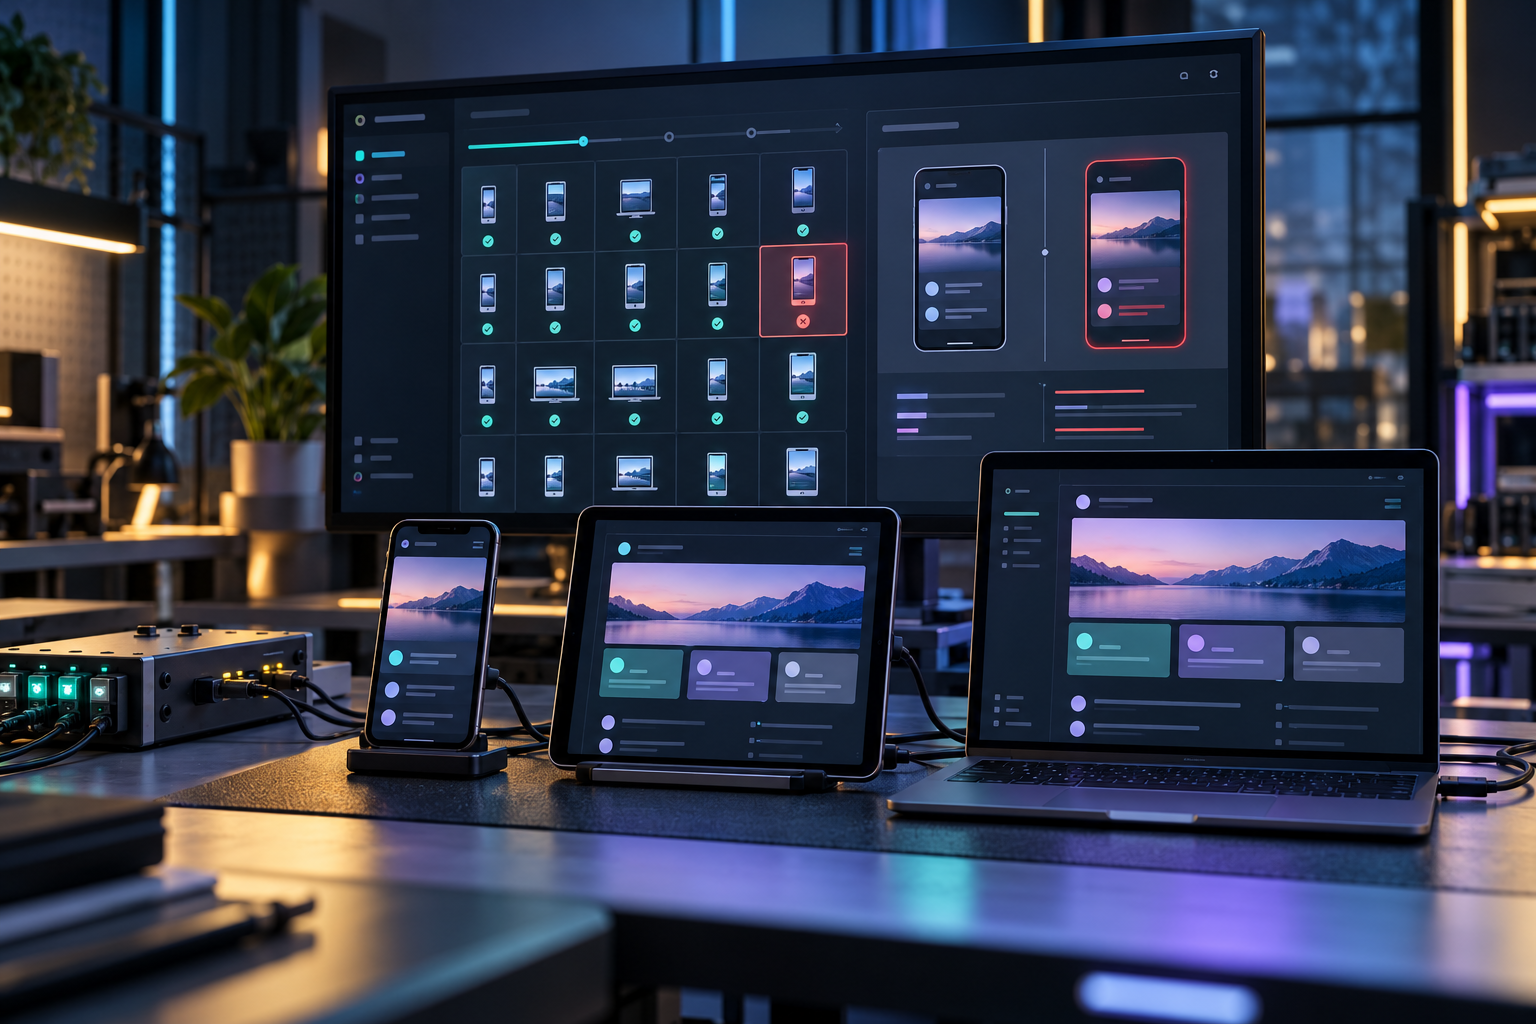
AI-Assisted Quality Engineering
Test what was asked for, not just what was built.
Use AI to design tests from requirements, automate them responsibly and catch the failures AI-generated code tends to hide, with evidence your team can trust.
AI TEACHING PERSPECTIVES · Meet the team


AI-generated code looks finished. It compiles, it is tidy, and it often arrives with tests the same model wrote — tests that confirm what the code does, not what anyone asked for. That makes independent, requirement-based testing more important than ever.
This course shows QA and test engineers how to use AI to design, automate and explore faster while keeping the test oracle where it belongs: in the requirements. You will also learn to test features that are powered by AI themselves.
Use the controls inside the presentation to start. Scratch answers stay only while this page is open. This activity does not automatically complete a lesson or pass an assessment. If media stops after a long break, reload this page.
One step closer.
With every module.
6 modules · 0 published lessons
Open a module to explore its lessons.
01LEARNING MODULE · ≈3 hoursQuality when code is cheap0 lessons · Week 1
Understand how AI-generated code fails and why tests written from the code cannot find those failures.
Objectives
- Describe typical failure patterns of AI-generated code.
- Explain why tests derived from an implementation cannot reveal an intent gap.
- Make the case for QA involvement before implementation starts.
Topics
- Plausible but wrong: how AI code fails
- Self-confirming tests
- Shifting quality left with specifications
- QA’s role in specification reviews
Concepts
Self-confirming test
A test written from the implementation, which passes because it repeats the code’s assumptions.
Test oracle
The source that decides what the correct result is: a requirement, a rule or an agreed example.
Shift-left
Moving quality work earlier, to requirements and design, where defects are cheaper to remove.
Exercise
Review an AI-written feature together with its AI-written tests.
Deliverable
A list of defects and of tests that only confirm the implementation.
Lesson material is being prepared for this module.
02LEARNING MODULE · ≈4 hoursTest design from requirements0 lessons · Week 1
Derive test cases from requirements with proven techniques, and use AI to expand and critique them rather than replace them.
Objectives
- Apply equivalence partitioning, boundary values, state-transition and decision-table testing.
- Use AI to propose additional cases and challenge your design.
- Prioritise tests by risk.
Topics
- Equivalence partitioning and boundary-value analysis
- State-transition and decision-table testing
- Risk-based prioritisation
- Four kinds of case: positive, negative, boundary and regression
- Prompts that generate cases with requirement IDs
Concepts
Boundary value
An input at the edge of a valid range, where off-by-one and time-zone defects hide.
Risk-based testing
Ordering test effort by the likelihood and impact of failure.
Regression case
A test that reproduces a past defect so it cannot return unnoticed.
Exercise
Design tests for the registration deadline and the duplicate-payment rule.
Deliverable
A test design with case IDs linked to requirements.
Lesson material is being prepared for this module.
03LEARNING MODULE · ≈4 hoursAutomation with AI assistance0 lessons · Week 2
Generate automated tests with an assistant, then review them as carefully as production code.
Objectives
- Generate API and UI tests with an AI assistant.
- Review generated tests for weak assertions, shared state and hidden assumptions.
- Diagnose and remove flaky tests.
Topics
- Generating API and UI tests, for example with Playwright or pytest
- Reviewing generated tests: assertions, data and isolation
- Fixtures, page objects and maintainability
- Flaky tests and their root causes
- Test data management
Concepts
Flaky test
A test that passes and fails without any change to the code under test.
Test fixture
The controlled setup a test runs in: data, configuration and state.
Assertion strength
How much a check actually proves. “Status is 200” proves far less than “exactly one registration exists”.
Exercise
Automate the critical registration cases.
Deliverable
A test suite with a review note for every generated test.
Lesson material is being prepared for this module.
04LEARNING MODULE · ≈4 hoursExploratory testing and reviewing AI changes0 lessons · Week 2
Explore systematically, review changes against the specification and write bug reports that people and agents can act on.
Objectives
- Write and run exploratory test charters.
- Use AI to suggest risk areas and attack ideas.
- Review a change against the specification and detect drift.
Topics
- Session-based exploratory testing
- AI-suggested risk areas and test ideas
- Reviewing pull requests against requirements
- Implementation drift
- Bug reports an agent can reproduce and fix
Concepts
Test charter
A short mission for an exploratory session: what to explore, with which resources, to find what.
Implementation drift
The gap that opens when code changes and the specification does not.
Reproducible bug report
Steps, data, expected and actual result, precise enough for someone else to see the defect.
Exercise
Explore a deliberately flawed patch to the registration service.
Deliverable
Session notes and three reproducible bug reports.
Lesson material is being prepared for this module.
05LEARNING MODULE · ≈4 hoursTesting AI-powered features0 lessons · Week 3
Test features whose output is not deterministic: chat assistants, summaries and recommendations.
Objectives
- Test non-deterministic output with properties and rubrics.
- Build and maintain an evaluation set.
- Probe for prompt injection and harmful output.
Topics
- Property-based and rubric-based checks
- Evaluation sets and baselines
- Using a model as a grader, and calibrating it
- Prompt injection and misuse tests
- Regression testing for model and prompt changes
Concepts
Evaluation set
A fixed set of realistic inputs with expected behaviour, run against every version.
Rubric
Explicit criteria for judging an output that has no single correct answer.
Prompt injection
Input that tries to override a model’s instructions, directly or through retrieved content.
Exercise
Test the AI course-advisor assistant.
Deliverable
An evaluation set with rubric and results, and a safety test log.
Lesson material is being prepared for this module.
06LEARNING MODULE · ≈4 hoursQuality evidence and release decisions0 lessons · Week 3
Turn test results into evidence a team can make a release decision on.
Objectives
- Build a requirement-to-evidence matrix.
- Define quality gates for continuous integration.
- Write a release recommendation that states residual risk.
Topics
- The traceability matrix
- Coverage that matters, and coverage that does not
- Quality gates in CI
- Communicating risk to non-testers
- Monitoring after release
Concepts
Quality gate
An automated or manual check that must pass before a change moves forward.
Residual risk
The risk that remains after testing, stated openly rather than hidden.
Release recommendation
QA’s written view on whether to release, based on evidence and residual risk.
Exercise
Prepare the release evidence for the registration feature.
Deliverable
A traceability matrix and a release recommendation.
Lesson material is being prepared for this module.
The course,
in context.
Explore the approach, expectations and practical details. These are public course notes, separate from your learning modules.
PUBLIC COURSE GUIDEWho this is for
- QA engineers, testers and test automation engineers.
- Developers responsible for testing their own AI-assisted changes.
- Quality leads defining test strategy for AI-assisted teams.
Before you begin
- Experience designing or executing software tests.
- Basic scripting in any language helps for the automation module; templates are provided.
- Access to an AI assistant; no specific vendor or test framework is required.
What you will learn
- Recognise how AI-generated code and tests fail.
- Derive test cases from requirements with classic techniques and AI support.
- Generate and review automated tests responsibly.
- Explore systematically and detect implementation drift.
- Test AI-powered features with evaluation sets and rubrics.
- Present quality evidence for release decisions.
Applied assignments
Test design pack
Requirement-linked test cases using boundary, state and decision-table techniques.
Automation and exploration pack
A reviewed automated suite, exploratory session notes and reproducible bug reports.
AI feature evaluation
Evaluation set, rubric, results and a safety test log for an AI assistant.
Your capstone project
Prove the registration service and its AI assistant
Capstone brief
You receive a specification, an AI-generated implementation and its AI-generated tests. Design independent tests from the requirements, automate the critical ones, explore for drift, evaluate the AI course assistant, and deliver a traceability matrix with a release recommendation.
Assessment
A 60-minute scenario exam: design boundary and state tests for a rule, critique an AI-generated test suite, and write a release recommendation from mixed evidence.
What you will produce
- Test design template
- Generated-test review checklist
- Exploratory charter and bug report templates
- AI feature evaluation template
- Traceability matrix and release recommendation templates
The method, explained
Keep the oracle independent
The most important question in testing is who decides what “correct” means. When the same AI writes the code and the tests, the answer is quietly “the code”. This course keeps the oracle where it belongs: in requirements, rules and agreed examples.
Three moves
Test from intent. Derive cases from the specification with proven techniques — boundaries, states, decision tables, risk — before you look at the implementation.
Let AI accelerate, not decide. Use assistants to expand case lists, draft automation and suggest attack ideas. Review every generated test as you would review production code.
Report evidence, not activity. A release decision needs a traceability matrix and an honest statement of residual risk, not a count of test cases.
Testing AI features
When the product itself uses a model, outputs vary. You will replace exact assertions with properties, rubrics and evaluation sets, and add safety tests for prompt injection and misuse.
How the case runs
Throughout the course you work on one realistic case: the course-registration and payment flow of a small learning platform, plus an AI-powered assistant that helps visitors choose a course. Developers meet the same case in Spec-Driven Development, so teams that learn together practise on the same material.
Course glossary
Test oracle
The source that decides the correct result.
Self-confirming test
A test that passes because it repeats the implementation’s assumptions.
Boundary value
An input at the edge of a valid range.
Flaky test
A test that passes and fails without any change to the code under test.
Implementation drift
The gap between evolving code and an unchanged specification.
Rubric
Explicit criteria for judging outputs without a single right answer.
Residual risk
The risk that remains after testing, stated openly.
Compare the approaches
Sources of test cases, compared
| Source | Strength | Weakness |
|---|---|---|
| Tests generated from the code | Fast, high line coverage | Confirm the implementation, including its mistakes |
| Tests designed from requirements | Find intent gaps and missing behaviour | Only as good as the requirements |
| Exploratory testing | Finds what nobody thought to specify | Hard to repeat without good notes |
| Production monitoring | Real users, real data | Finds problems after users do |
| Evaluation sets for AI features | Measure quality of variable output | Must be kept representative |
A strong strategy uses all five, with requirement-based tests as the backbone and AI as an accelerator at every step.
Teaching perspective
This course is developed with our AI teaching personas and reviewed by the experienced software developers behind the lab. The personas are creative identities for AI-assisted perspectives, not human instructors.
- Verity — Testing & Reliability Specialist: how would we notice if this were wrong?
- Prism — Data & Model Analyst: what does the evidence actually support?
- Forge — Software Engineer: can we make this simpler and prove it works?
Human responsibility stays human: we decide what belongs in the course, test the examples and correct what is wrong.
Your effort.
Made official.
Complete the required lessons and pass any required assessments to earn your AI-Assisted Quality Engineering certificate of completion.
Download your PDF and share a public verification link. Each issued certificate has its own code and QR code. This is an AI Pioneers completion certificate, not external accreditation.
Loading certificate preview…
Generated with the same template as the awarded certificate. If the preview is unavailable on your device, use “Open sample PDF” above.
Experiences.
In their own words.
Reviews are submitted by enrolled learners and checked before publication. Ratings include approved reviews only. Critical feedback is welcome; spam, abuse and unrelated content are not.
No published reviews yet. Your experience could help the next learner.